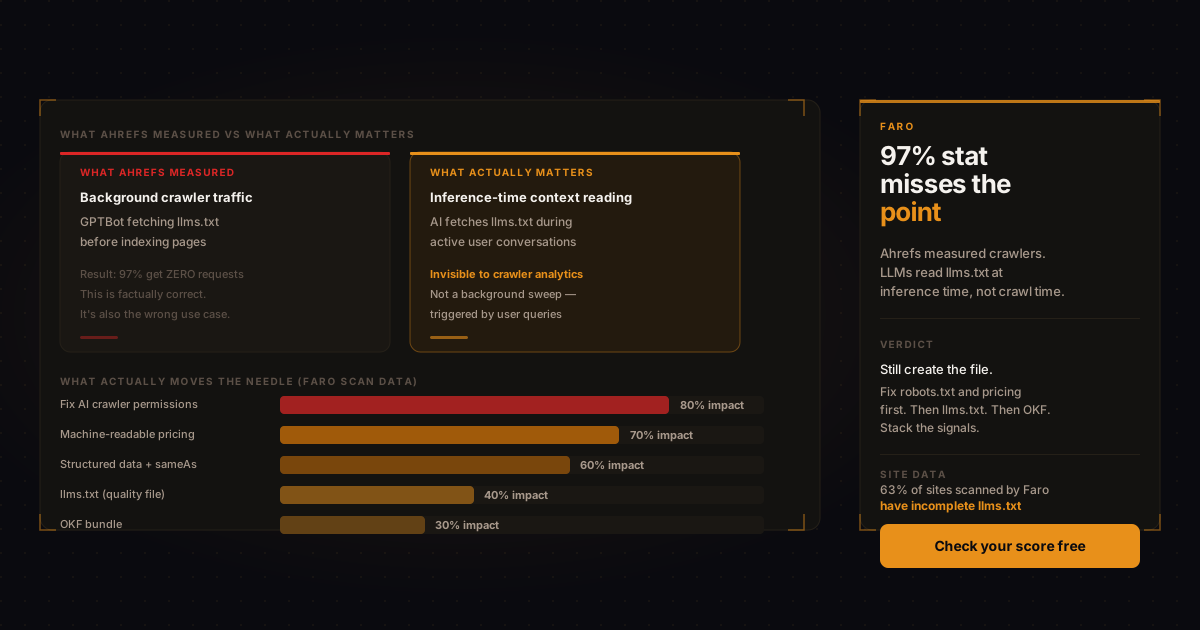
Ahrefs checked the 137,210 domains in Ahrefs Web Analytics that had traffic in May 2026. About 38,000 of them publish a valid llms.txt file, and 97% of those files got no requests at all that month. Not from AI crawlers, not from AI assistants fetching pages for a user, not from people. The file does very little today. Faro still publishes one, because it takes minutes, and puts the real effort elsewhere.
Key takeaways
- Ahrefs checked 137,210 domains in May 2026. About 38,000 publish a valid llms.txt file, and 97% of those files got zero requests.
- The study counted every request, including AI assistants such as ChatGPT-User and Claude-User that fetch pages on behalf of a user.
- The files that did get traffic received about 22,000 requests in total. AI bots of every kind made 19.5% of them, and AI retrieval bots made 1.1%.
- Faro's position: keep a basic llms.txt because it is cheap, link it, and spend the real time on crawler access, answer-first pages and visible prices.
- In the Faro Registry, 29% of sites publish llms.txt, 75% fail the answer-first check and 31% show no prices an AI can read.
What did the Ahrefs llms.txt study actually find?
Ahrefs used its Web Analytics and Bot Analytics data to look at server logs and live traffic for every domain in Ahrefs Web Analytics that received traffic in May 2026: 137,210 domains. It checked each domain root for an llms.txt file returning HTTP 200, and confirmed the files were real Markdown rather than HTML error pages. About 38,000 domains passed, 28% of the sample. Of those, 97% saw no requests for the file at all during the month.
The study was written by Louise Linehan, with Xibeijia Guan contributing, and published on June 15, 2026. You can read the full Ahrefs llms.txt study for the charts and the method.
The other 3% of files, on about 1,100 domains, received roughly 22,000 requests between them. That is around 20 requests per file for the whole month. Ahrefs itself calls it a tiny pool.
Who requested the llms.txt files that did get traffic?
Mostly tools checking whether the file exists, not AI systems reading it. SEO audit tools were the largest group, at 21.7% of requests. Add GEO and AEO tools, the kind of scanner Faro runs, and audit-style tools made 27.5% of requests between them.
| Requester (Ahrefs category) | Share of requests |
|---|---|
| SEO audit tools | 21.7% |
| Other and unidentified | 14.9% |
| General web crawlers, including Googlebot | 13.1% |
| Tech profiling tools | 11.6% |
| AI agents and agentic infrastructure | 10.5% |
| GEO and AEO tools | 5.8% |
| AI training crawlers | 5.3% |
| Humans | 4% |
| llms.txt discoverability bots | 3.6% |
| Service and social bots | 2.9% |
| Research bots | 2.7% |
| AI assistants, fetching for a user | 2.5% |
| AI retrieval bots | 1.1% |
Ahrefs puts all AI categories together at 19.5% of requests. AI retrieval bots, the group closest to AI search, made 1.1%. The AI traffic that did arrive came mostly from agents and training crawlers, not from systems answering a search.
Does the study miss AI tools reading llms.txt during a conversation?
No. An earlier version of this post argued that it did, and that argument does not hold. Ahrefs' AI assistants category covers bots that "browse the web on behalf of a user in response to a single query", with ChatGPT-User and Claude-User named as examples. Those fetches are in the data, at 2.5% of requests. Claude can fetch pages during a conversation, as covered in how Claude evaluates business websites for recommendations, and those fetches land in server logs like any other request. If models routinely read llms.txt mid-conversation, it would show up there.
Ahrefs also sets out its own limits. Its customers skew more technical and SEO-aware than the web at large, so it treats the 28% adoption figure as an upper bound. It measured the index file only, not the pages the file links to. And a fetch is not a read: a bot can request the file and never act on what is inside. Every figure in the study is a ceiling on real llms.txt use, not a floor.
Why does Faro still publish an llms.txt file?
Because it is cheap and the picture could change. A basic file takes minutes with a generator, costs nothing to host and does no harm. If OpenAI, Anthropic or Google start documenting llms.txt support, a site with a clean file is ready the same day. That is the whole case. It is a hedge, not a ranking factor.
Ahrefs lands somewhere similar in practice. Its verdict is that "the cons outweigh the pros right now", but its advice for anyone keeping a file is practical: check your own logs before investing further, let your website platform generate the file if it offers to, link the file so agents can find it, and treat it like code to offset the prompt injection risk. As the study puts it, agents fetch llms.txt when directed, not speculatively.
That linking point is the one almost nobody acts on. In Faro's scans, 3% of the 783 sites checked link their llms.txt from the homepage.
For the stronger case against bothering at all, read why AI crawlers ignore llms.txt 97% of the time. Most of it holds. Faro just thinks a file that takes minutes is worth keeping while the question stays open.
What matters more than llms.txt for AI visibility?
Whether AI systems can reach your pages, find the answer in your visible text, and identify your business correctly. Those are the gaps Faro's AI visibility checker finds most often. Across the 2,444 sites in the Faro Registry, scanned August 2026 to October 2026:
- 75% fail the answer-first check: their key pages do not answer their question in the opening lines (of 2,029 sites checked).
- 67% have no sameAs links tying the business to profiles such as LinkedIn, Wikidata or Crunchbase.
- 46% have no JSON-LD structured data.
- 31% show no actual prices an AI system can read.
- 13% block GPTBot, or likely block it through Cloudflare's bot settings.
- 71% have no llms.txt file (of 2,337 sites with a result).
The registry is the set of sites Faro has scanned, not a random sample of the web.
A note on structured data, because it is easy to oversell. Schema helps AI systems and agents work out who you are and what you sell. It is not a citation lever: Ahrefs tracked 1,885 pages that added JSON-LD and found AI citations barely moved. Add it for accuracy, not rankings.
What should you fix first?
- Check crawler access. If GPTBot, ClaudeBot or OAI-SearchBot is blocked in your
robots.txtor by your CDN, AI systems cannot read the pages you want cited. Use Faro's robots.txt analyzer to check your current setup. - Put the answer first. Make the opening lines of each key page answer the question that page exists for. That is the text an AI system is most likely to lift.
- Show real prices. AI agents comparing products for a buyer need numbers on the visible page, not "contact us". A
/pricing.mdfile helps agents that look for one. - Add Organization schema with sameAs links. It tells AI systems which business you are. The Faro AI Schema Creator builds the markup.
- Publish a basic llms.txt and link it. Say what you do, who it is for, your pricing summary and where your key pages are. The llms.txt generator does it in minutes, and the guide to using the llms.txt generator covers what to include and how to keep it current. Link it from your homepage so agents can find it.
- Add an OKF bundle if you have deep documentation. The Open Knowledge Format goes further than llms.txt with structured product, pricing and documentation files. 9% of registry sites have one. The Faro OKF Generator builds it.
What is the short answer on llms.txt?
Ahrefs found that 97% of llms.txt files got zero requests in May 2026, and it counted AI assistants and agents, not only crawlers. The file does little today. Keep a basic one because it is cheap, link it, and spend your real effort on crawler access, answer-first pages and visible prices.
Check your site against all 54 of Faro's checks at byfaro.ai. It takes about 30 seconds, and you do not need an account.
FAQ
Does llms.txt help with AI search visibility?
Not measurably, on current data. Ahrefs found 97% of llms.txt files got no requests in May 2026, and the little AI traffic the rest received came mostly from agents and training crawlers, not AI search. A basic file is cheap to keep. Do it after crawler access, answer-first pages and visible prices.
What did the Ahrefs llms.txt study actually find?
Ahrefs checked 137,210 domains with traffic in May 2026. About 38,000 publish a valid llms.txt file, and 97% of those got no requests at all that month. The files that did get requests received about 22,000 in total, and AI bots of every kind made 19.5% of them.
Did the Ahrefs study count ChatGPT and Claude fetching pages for a user?
Yes. Its AI assistants category covers bots that browse the web on behalf of a user, with ChatGPT-User and Claude-User as examples. They made 2.5% of requests to llms.txt files in the study.
Should I delete my llms.txt file?
No. A correct file does no harm and costs nothing to host. Link it from your homepage, review it like code, and stop there. Spend the rest of your time on the pages AI systems actually read.
How is llms.txt different from robots.txt?
robots.txt controls crawler access: which bots may fetch your pages and which are blocked. llms.txt is an optional plain-text summary of what your site contains and who it is for. Crawlers that respect robots.txt act on it. Very few AI systems request llms.txt at all.
Correction, October 15, 2026: an earlier version of this post said Ahrefs analyzed 3.7 million llms.txt files and counted only AI crawler user agents. The study covered 137,210 domains and counted every request, including AI assistants fetching pages for a user. This post has been rewritten to match the study.